Making LLM scoring repeatable enough to trust
The same input scored differently on every run. The fix was architectural, not a prompt tweak.
The problem
A system scoring thousands of items a day returned wildly different scores for identical inputs. Users would see their item judged differently depending on when it happened to be processed — not a variance you can explain away.
What I did
- Traced the inconsistency to its root: the model was inventing its own scoring criteria from scratch on every single request, so any shift in sampling moved the whole rubric.
- Split the job into the two phases it actually contains — deciding what to score on, which needs real reasoning, and applying that rubric, which is mechanical.
- Ran phase one on a strong model once per category to produce a fixed rubric, then handed every item to a cheap model that is only allowed to apply it.
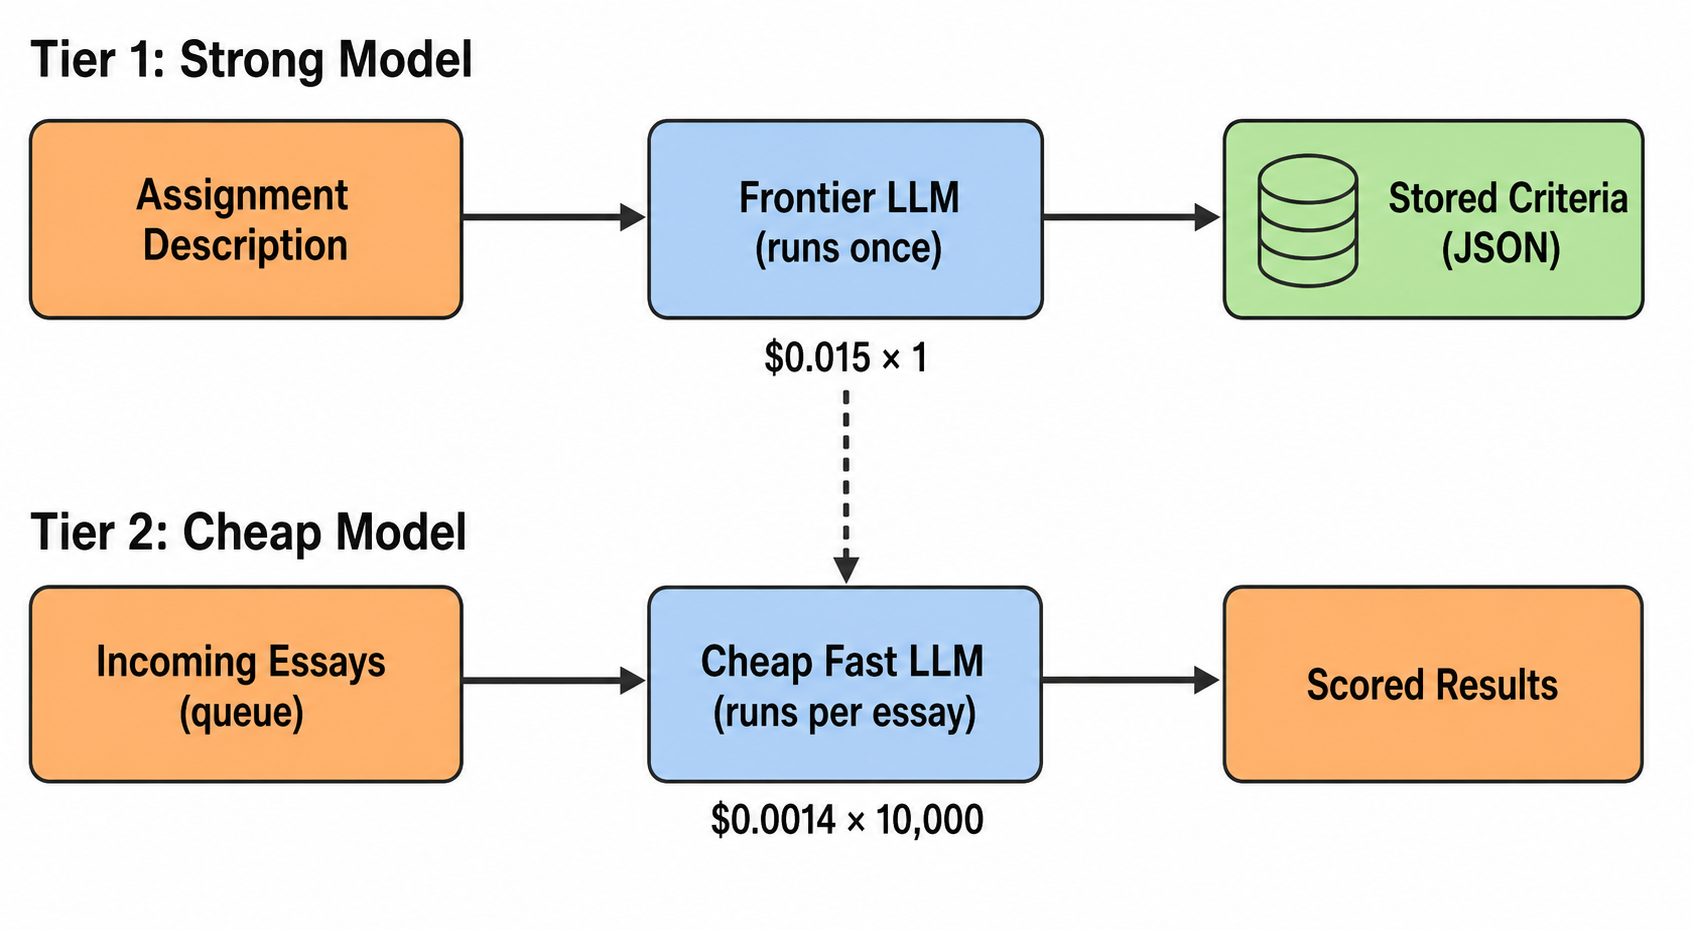
Two identical submissions now get identical scores, because the cheap model has no room to invent criteria. Consistency is what made the system defensible — and the expensive reasoning happens once per category instead of once per item.
The outcome
Read more
I wrote this one up in full: Splitting LLM Workload Between Strong Model and Cheap Model.