Choosing an LLM provider with numbers instead of vibes
Six providers, one real production prompt, and a 20x spread in daily cost.
The problem
A feature needed thousands of LLM calls per day for structured JSON generation. The decision was heading toward whichever model had the best reputation, which is a bad way to commit to a per-request bill.
What I did
- Took ten representative inputs and ran the actual production prompt — roughly 2,000 input tokens, structured JSON out — through six providers on personal credits.
- Instrumented every call through self-hosted Dify with LangSmith attached, so token counts, latency and cost were measured rather than estimated.
- Compared on the axes that matter at volume: cost per request, tail latency, and output consistency — not leaderboard rank.
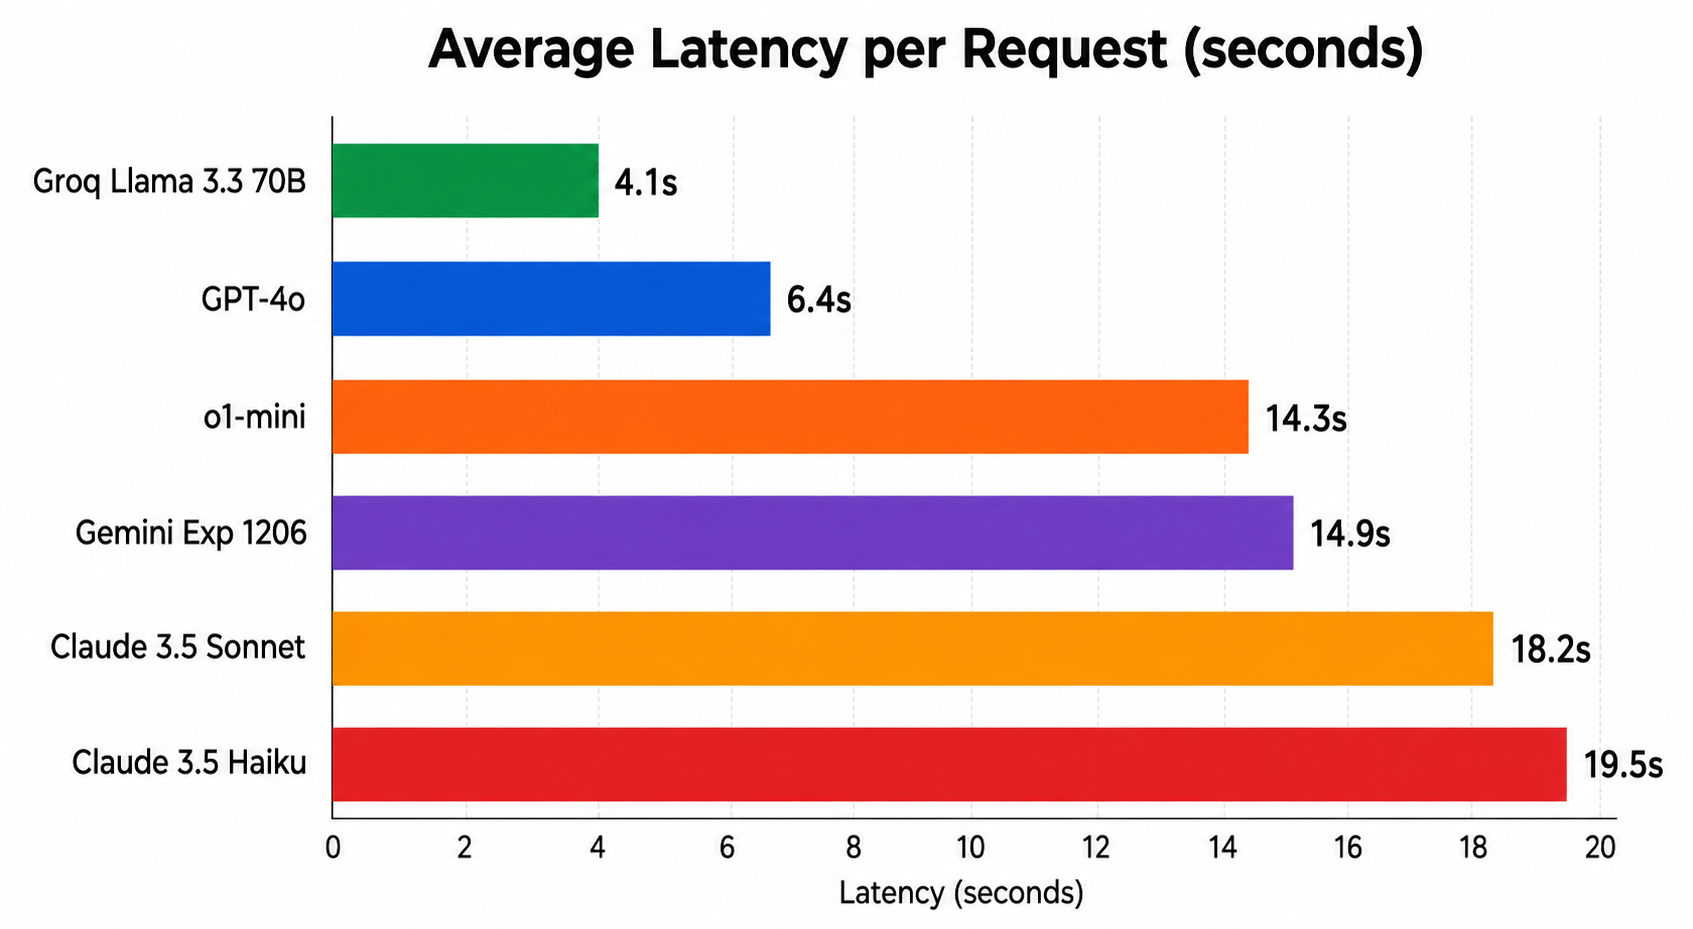
At 1,000 requests a day, o1-mini worked out to $29/day against $1.37/day on Groq, with a single worst-case request hitting $0.548 and 35.5 seconds. The benchmark also exposed that routing through an intermediary added latency variance nobody could control.
The outcome
Read more
I wrote this one up in full: Benchmarking 6 LLM Providers for Latency and Cost (December 2024).